Security. Independence. Precision.

The AI workspace that never phones home.

Document-grounded chat, an agentic coding IDE, and a design studio — plus translate and MCP hubs — one interface, running entirely inside your own network. Your models. Your hardware. Your rules.

Air-gap capable — works with zero outbound connectivity
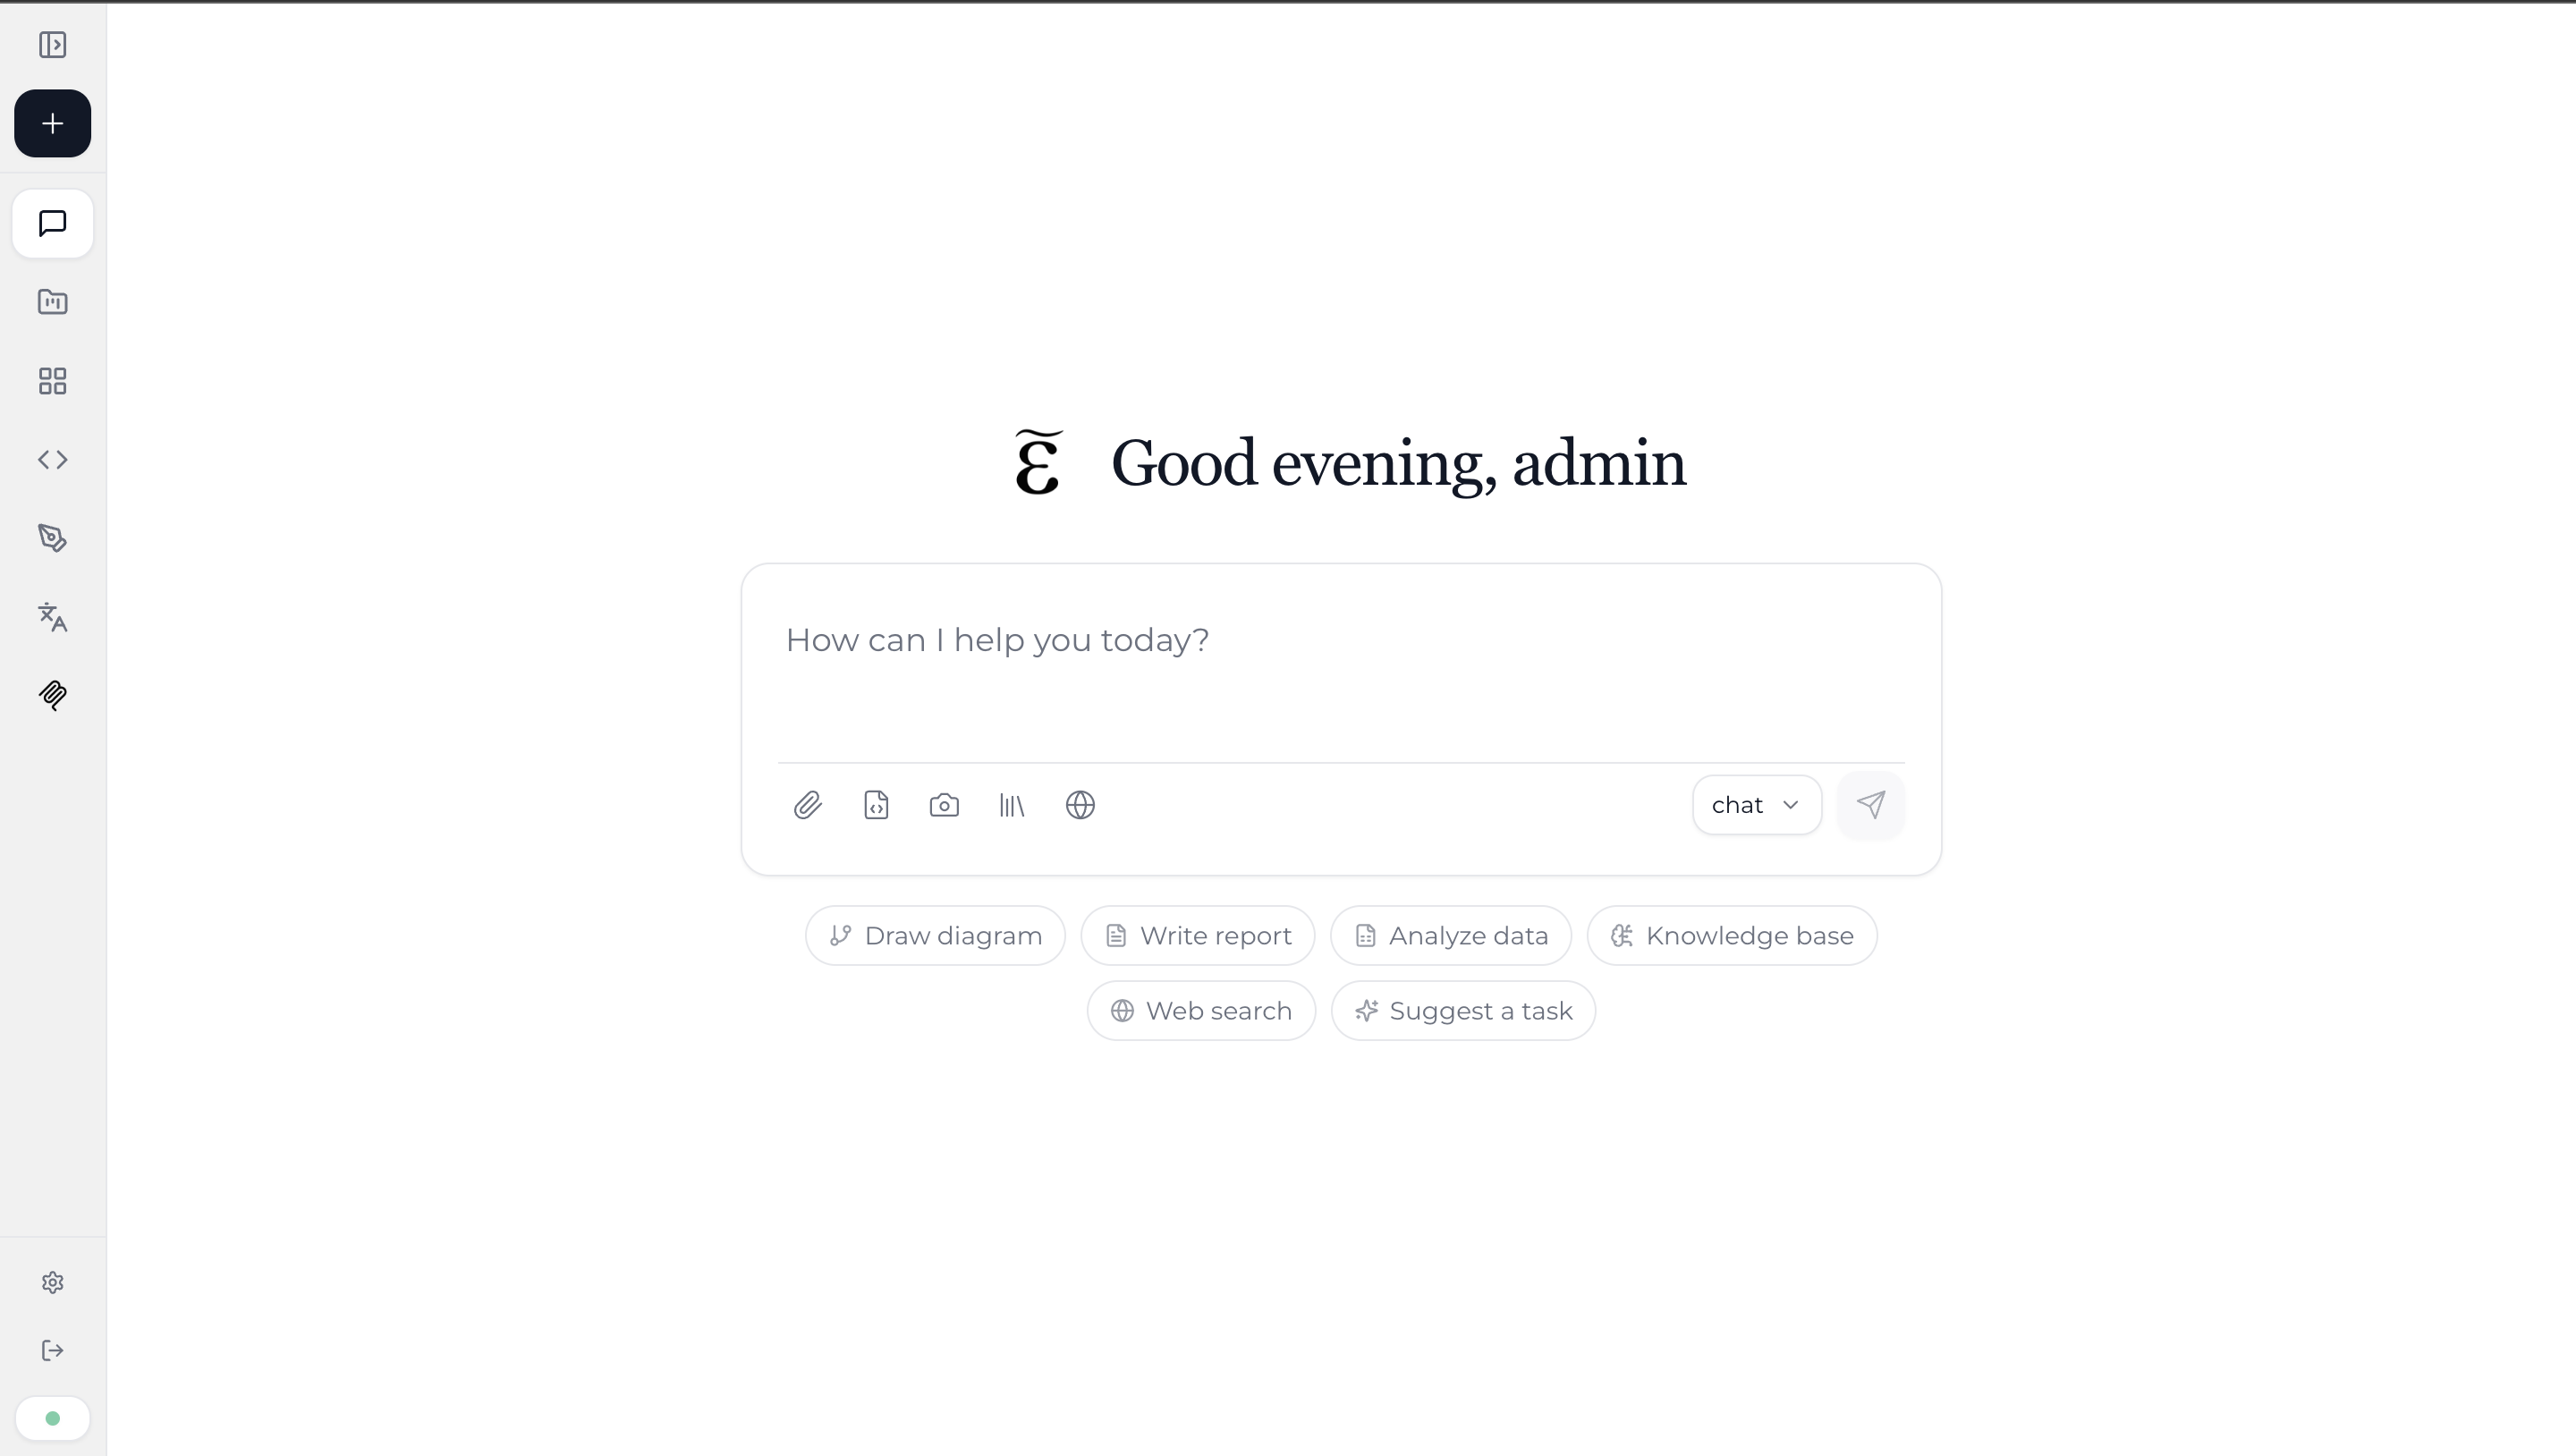
eleftheria.internal
Workspace overview assets/homepage.png · 1600×1000
0
Token context window
0
Canvas & print formats
0
Product hubs, one interface
0
Bytes sent to third parties
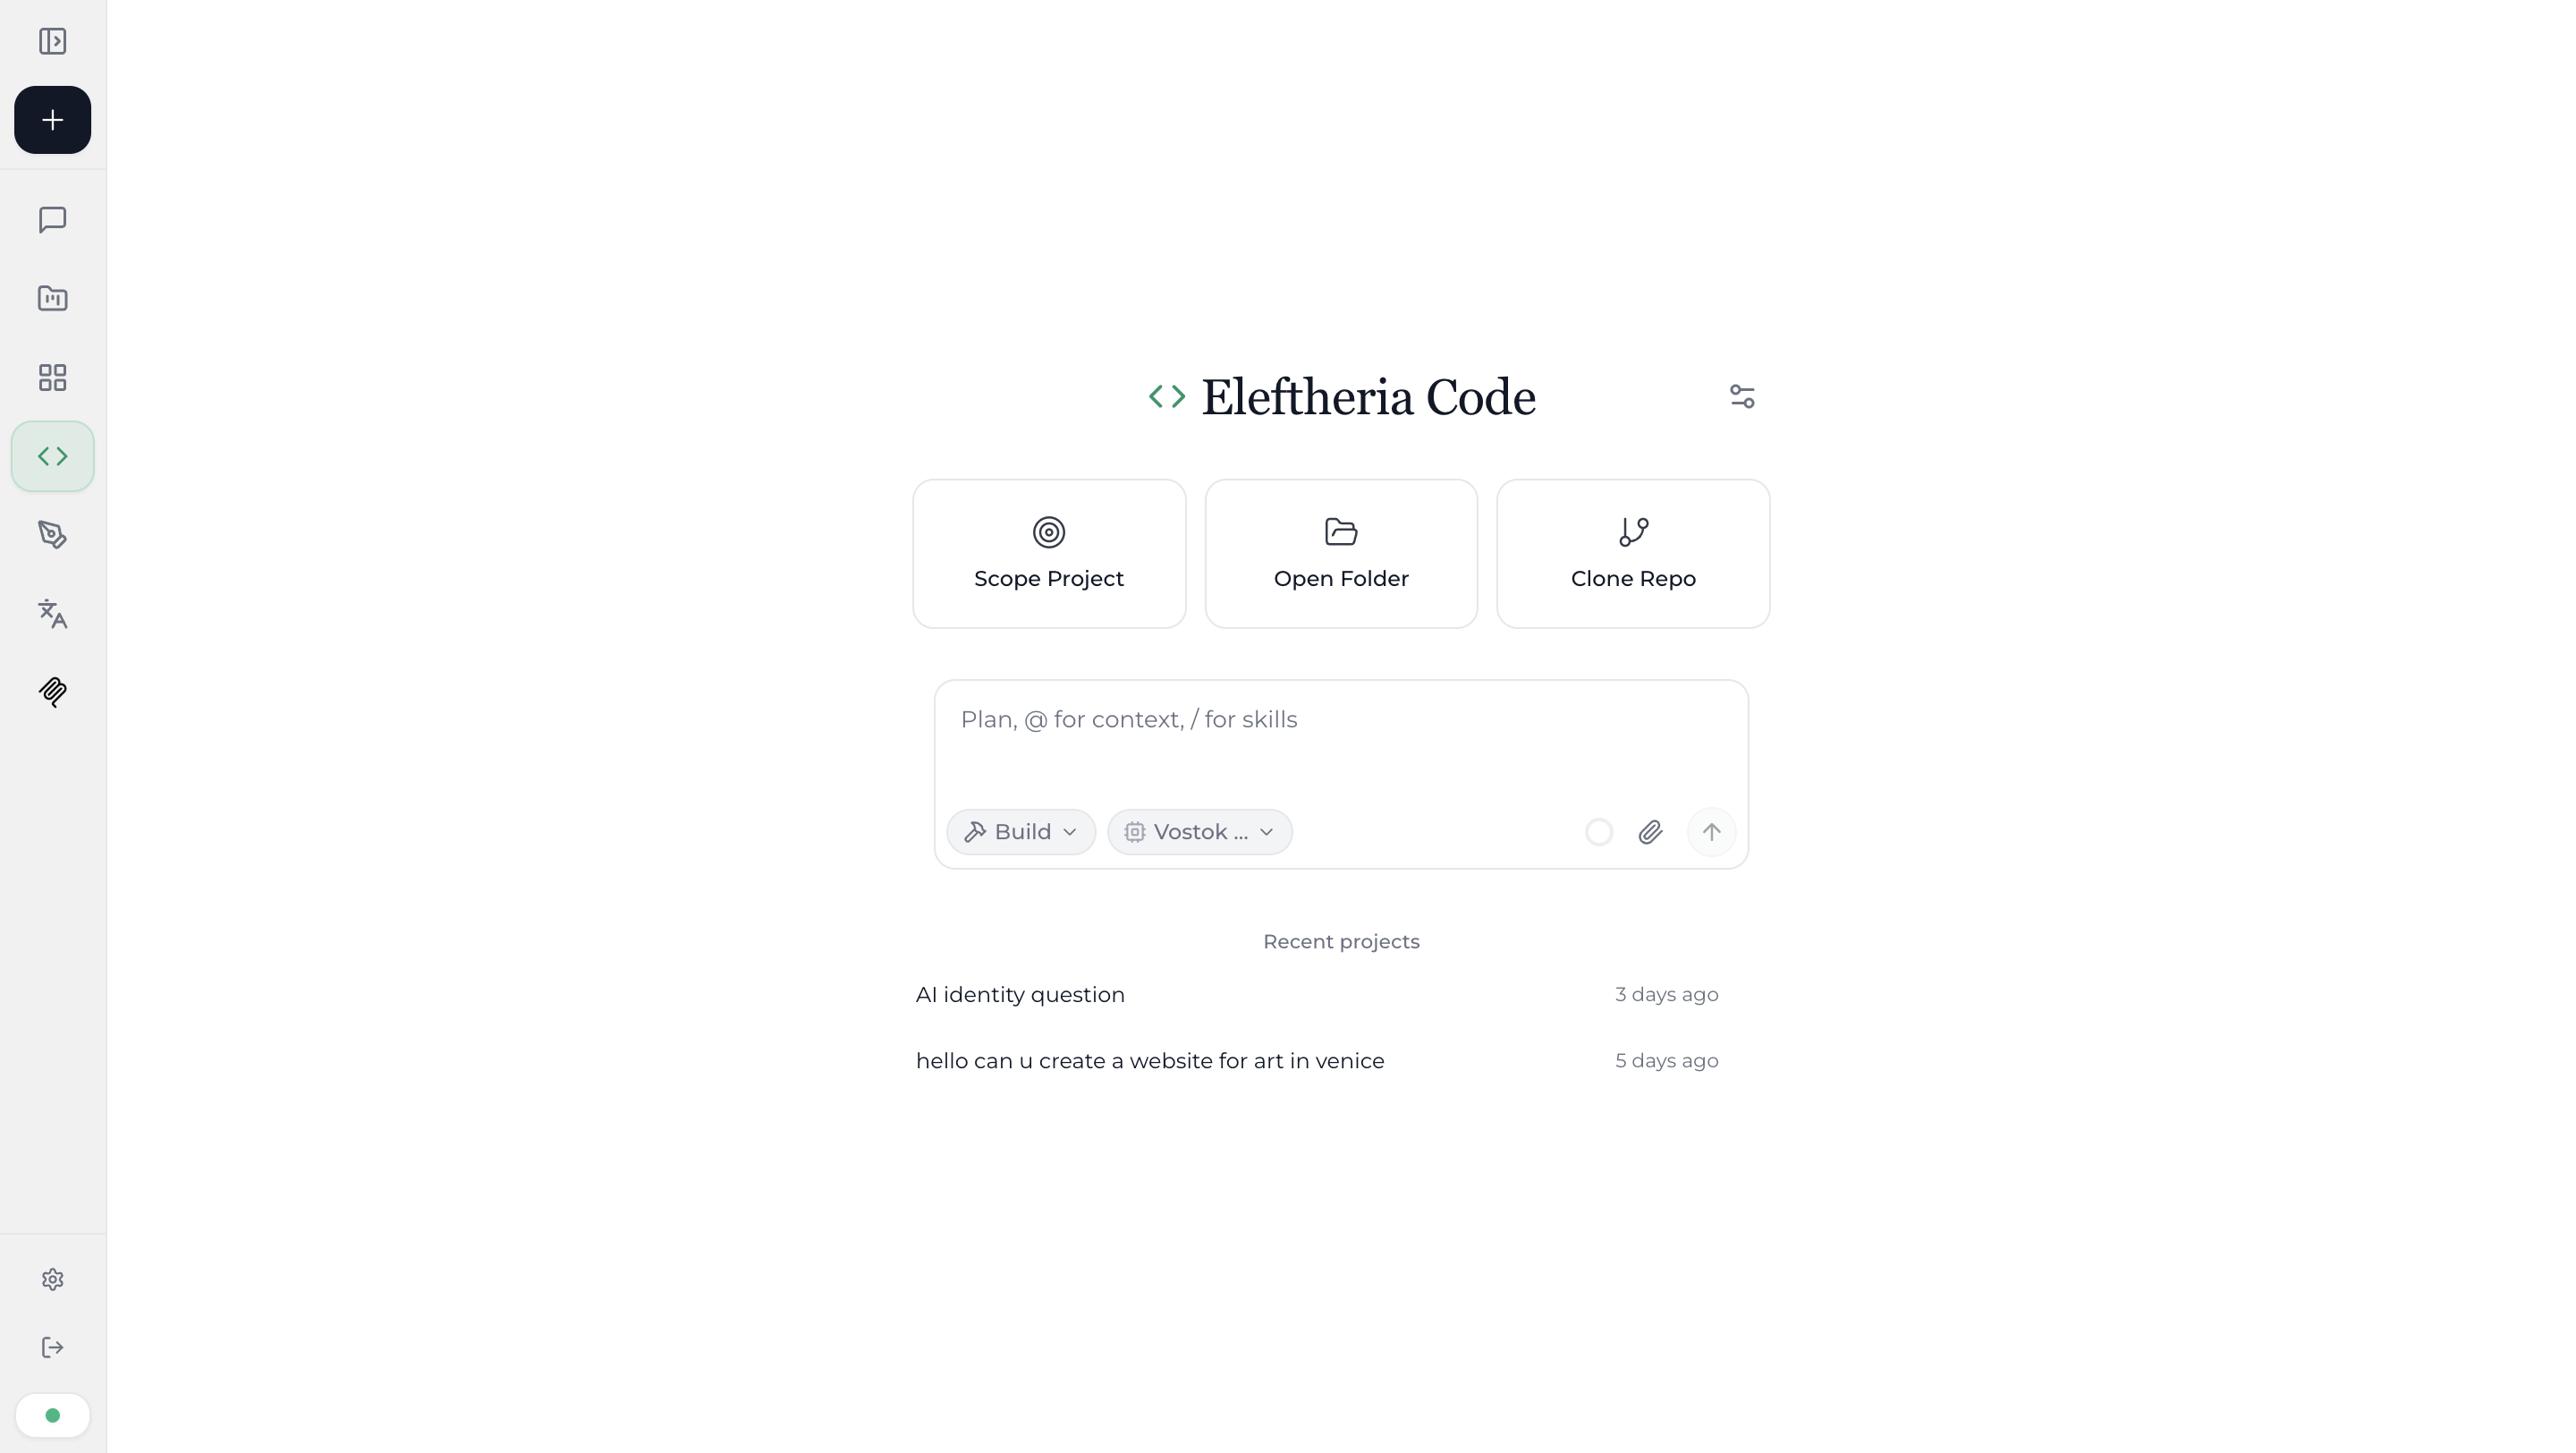
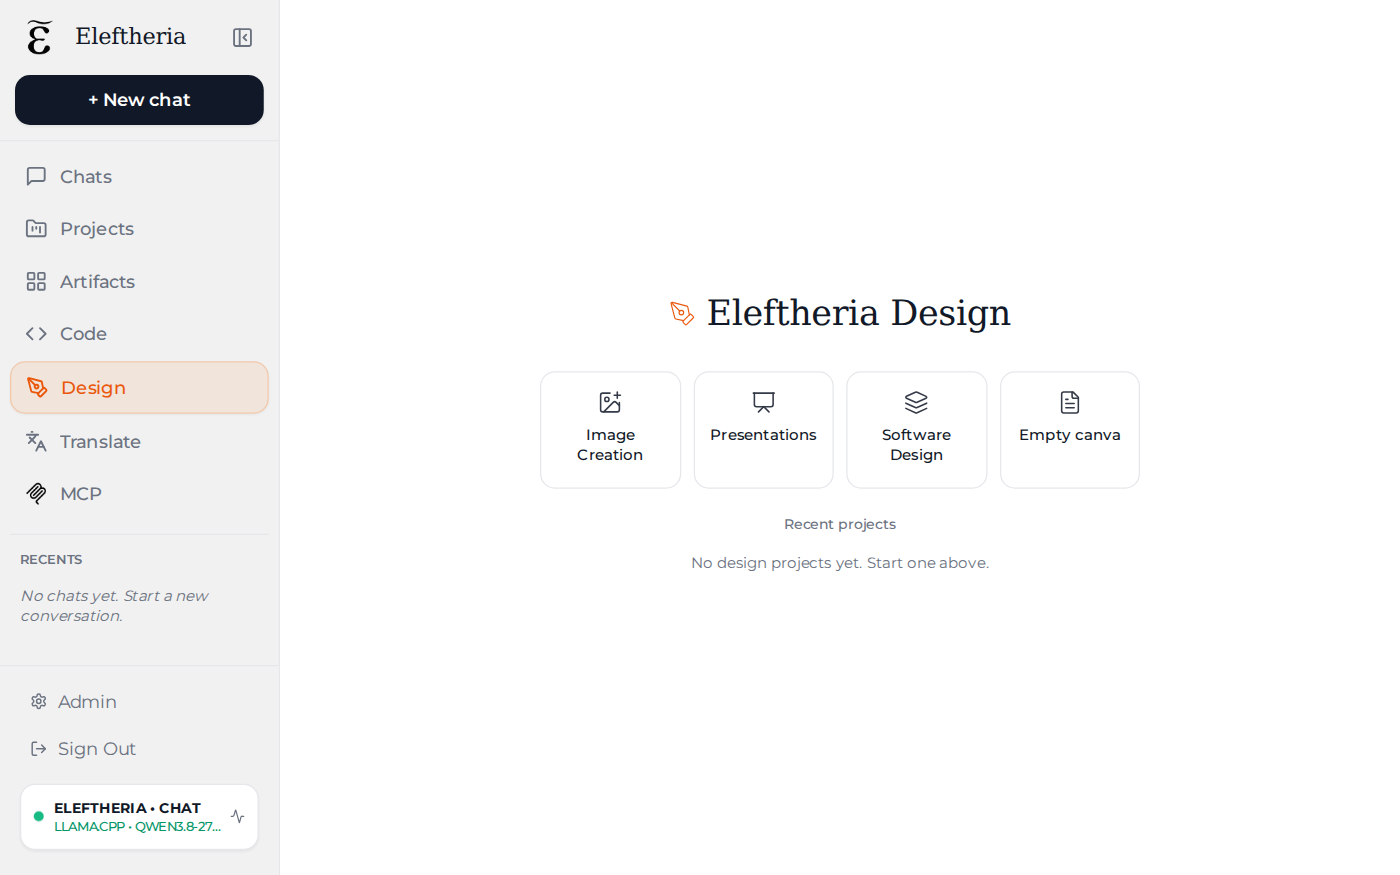
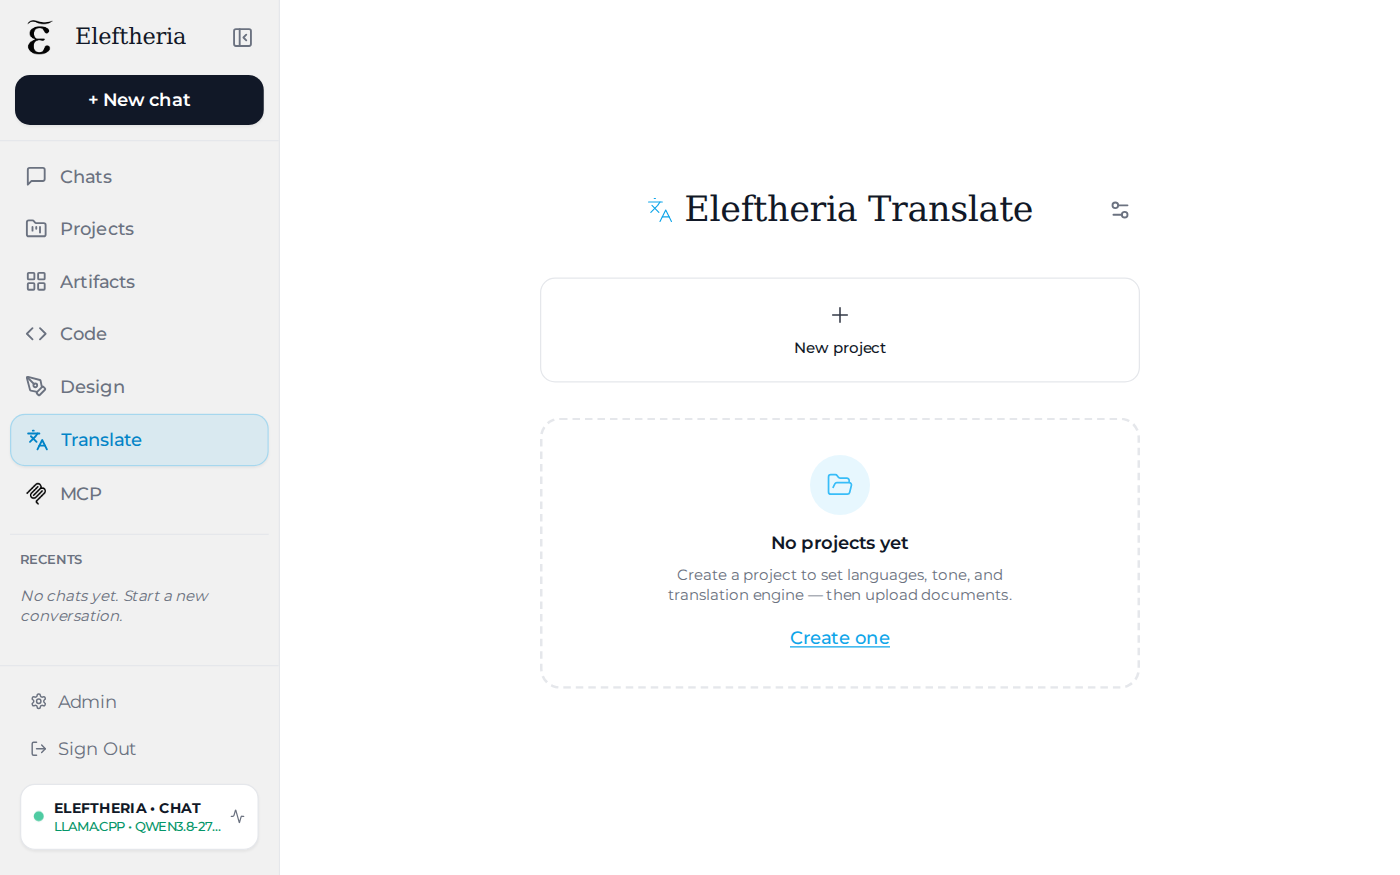
Product hubs

One interface, seven hubs.

Seven product hubs share one login, one permission model, and one set of files. Chat, code, and design are the daily drivers — and they hand work off to each other.

01

Answers grounded in your documents

Drop in a PDF, contract, or spreadsheet and ask questions against it. Retrieval runs on pgvector inside your database — the source text never leaves the machine it landed on.

PDF · DOCX · XLSX · CSV Knowledge Archives Vision MCP tools Answer verification Artifacts panel Attachments
Join the waitlist
eleftheria.internal / chat
Chat with artifact panel assets/homepage.png · 1400×875

MCP

Connect Model Context Protocol tool servers so agents can call your internal APIs and databases under group permissions.
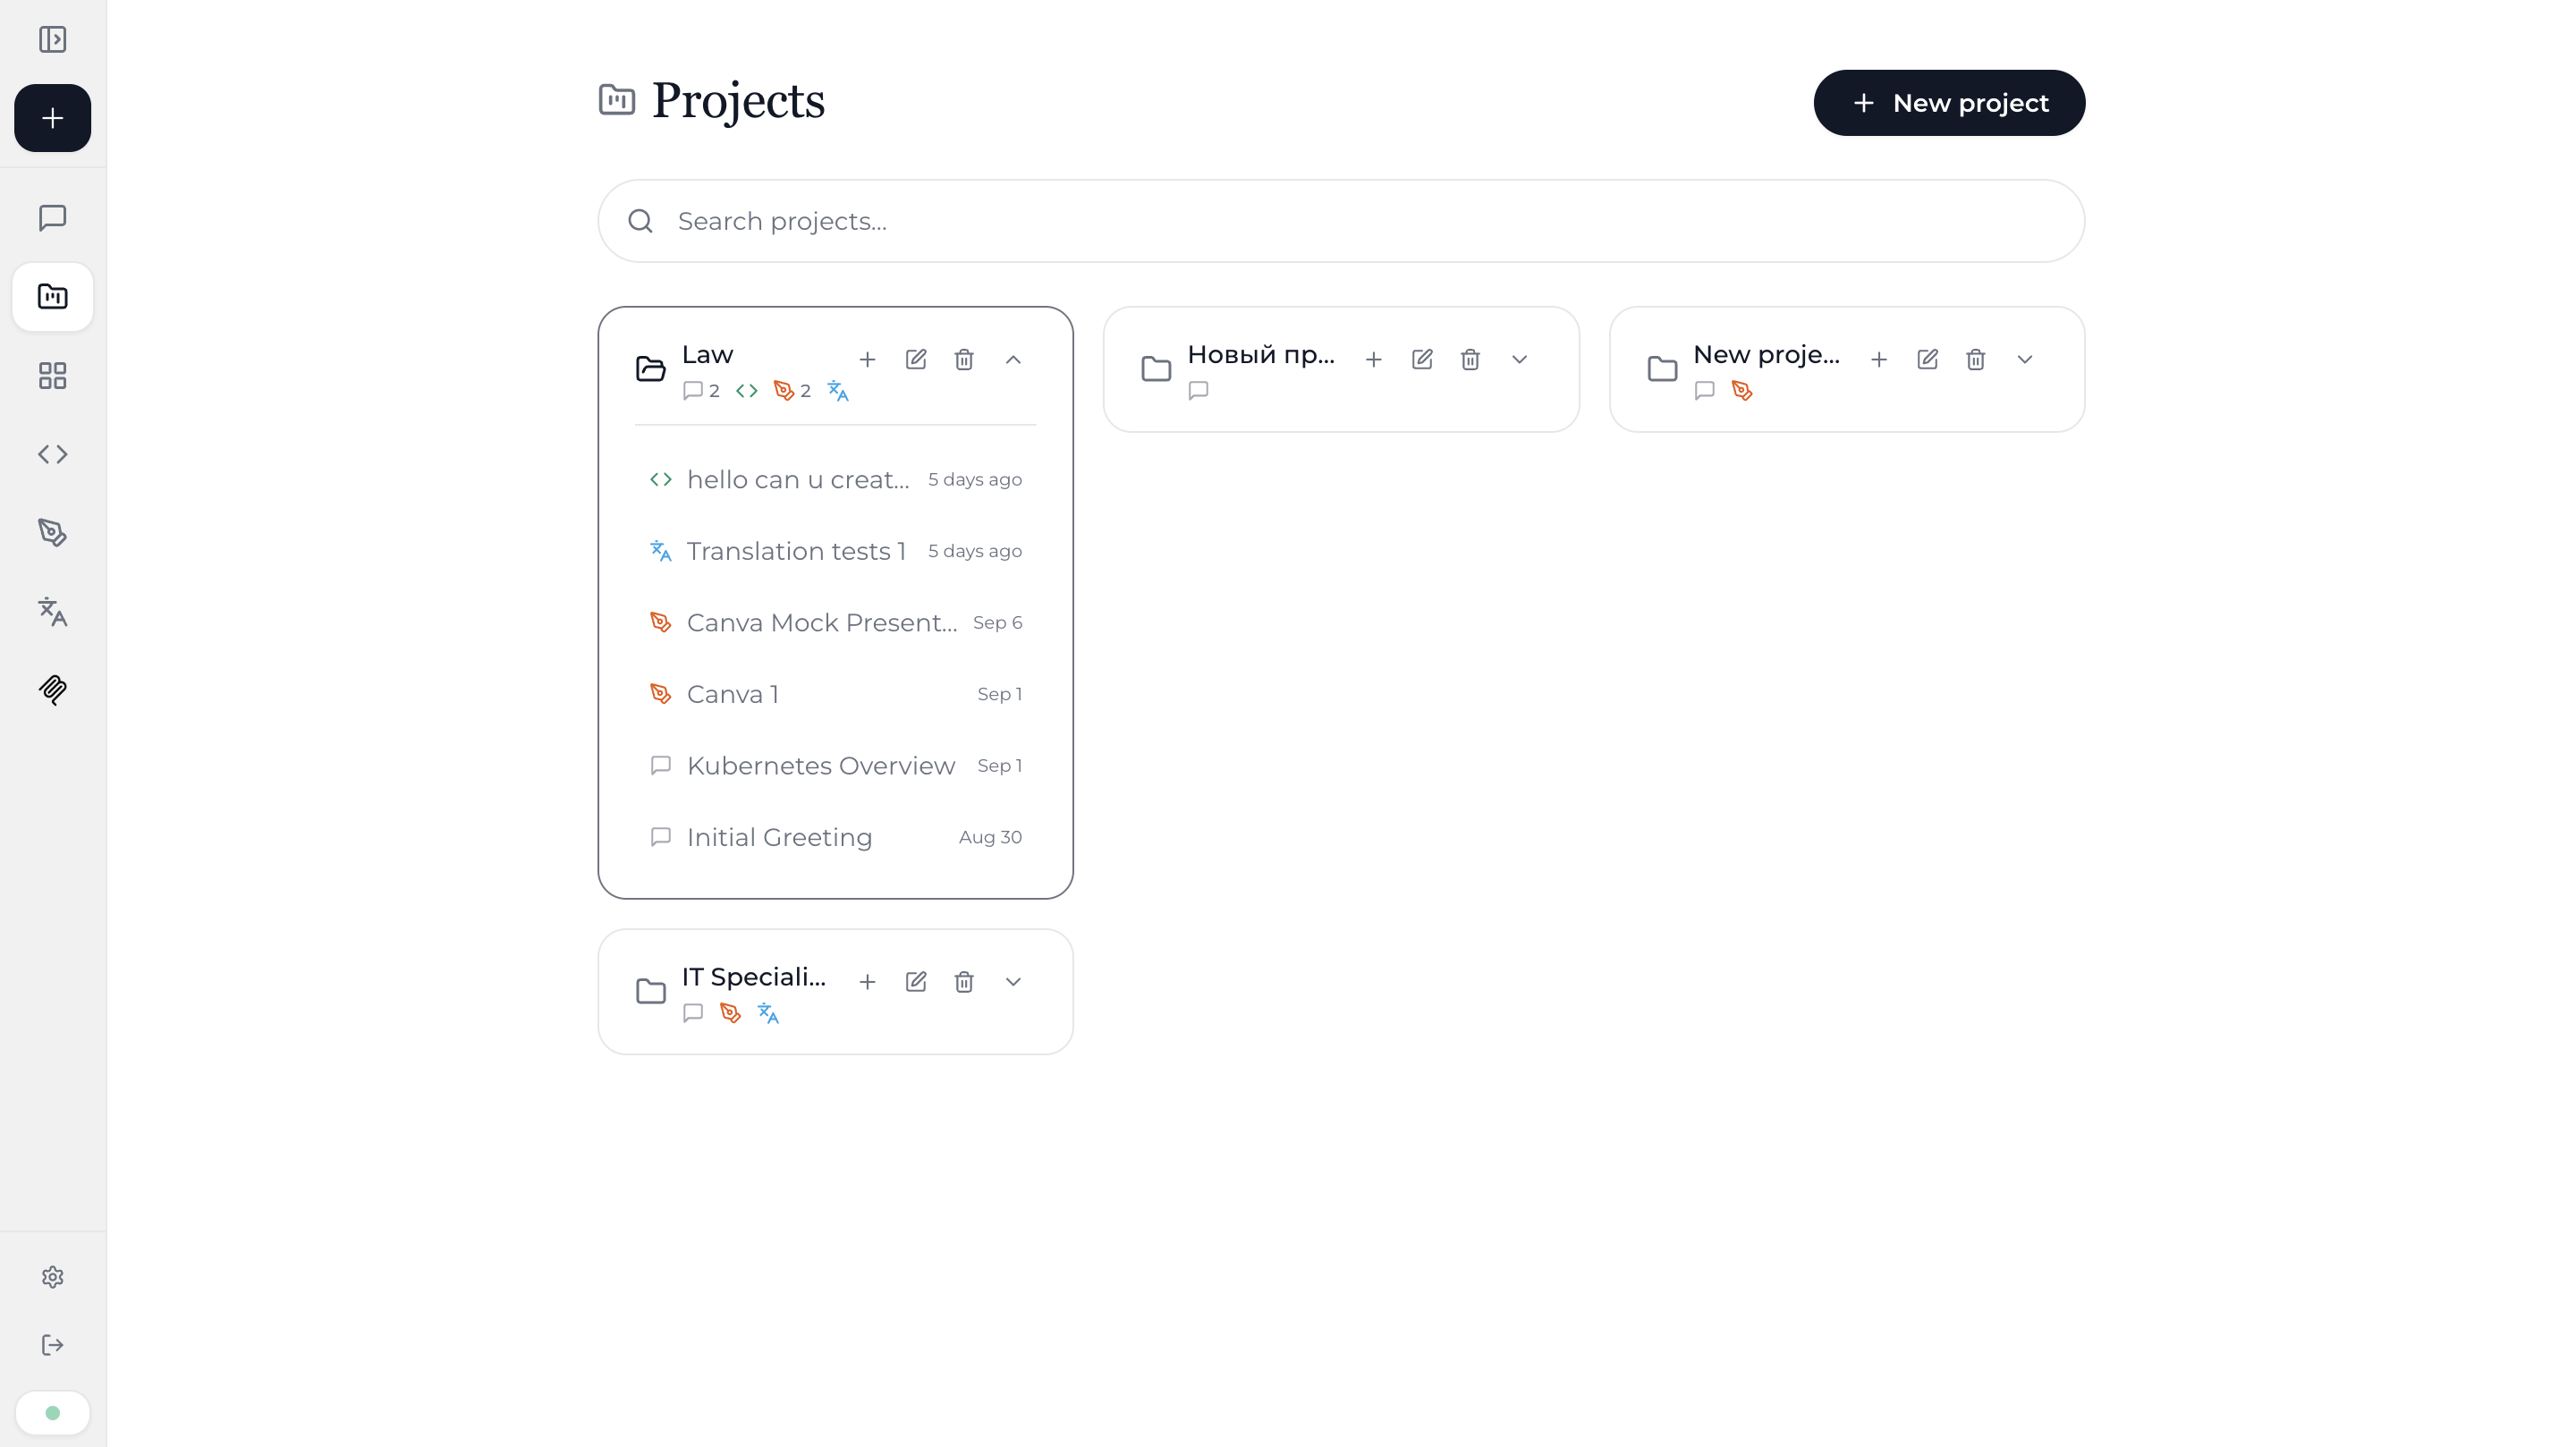
Projects

Organize chats, files, and code workspaces under shared project boundaries for teams.
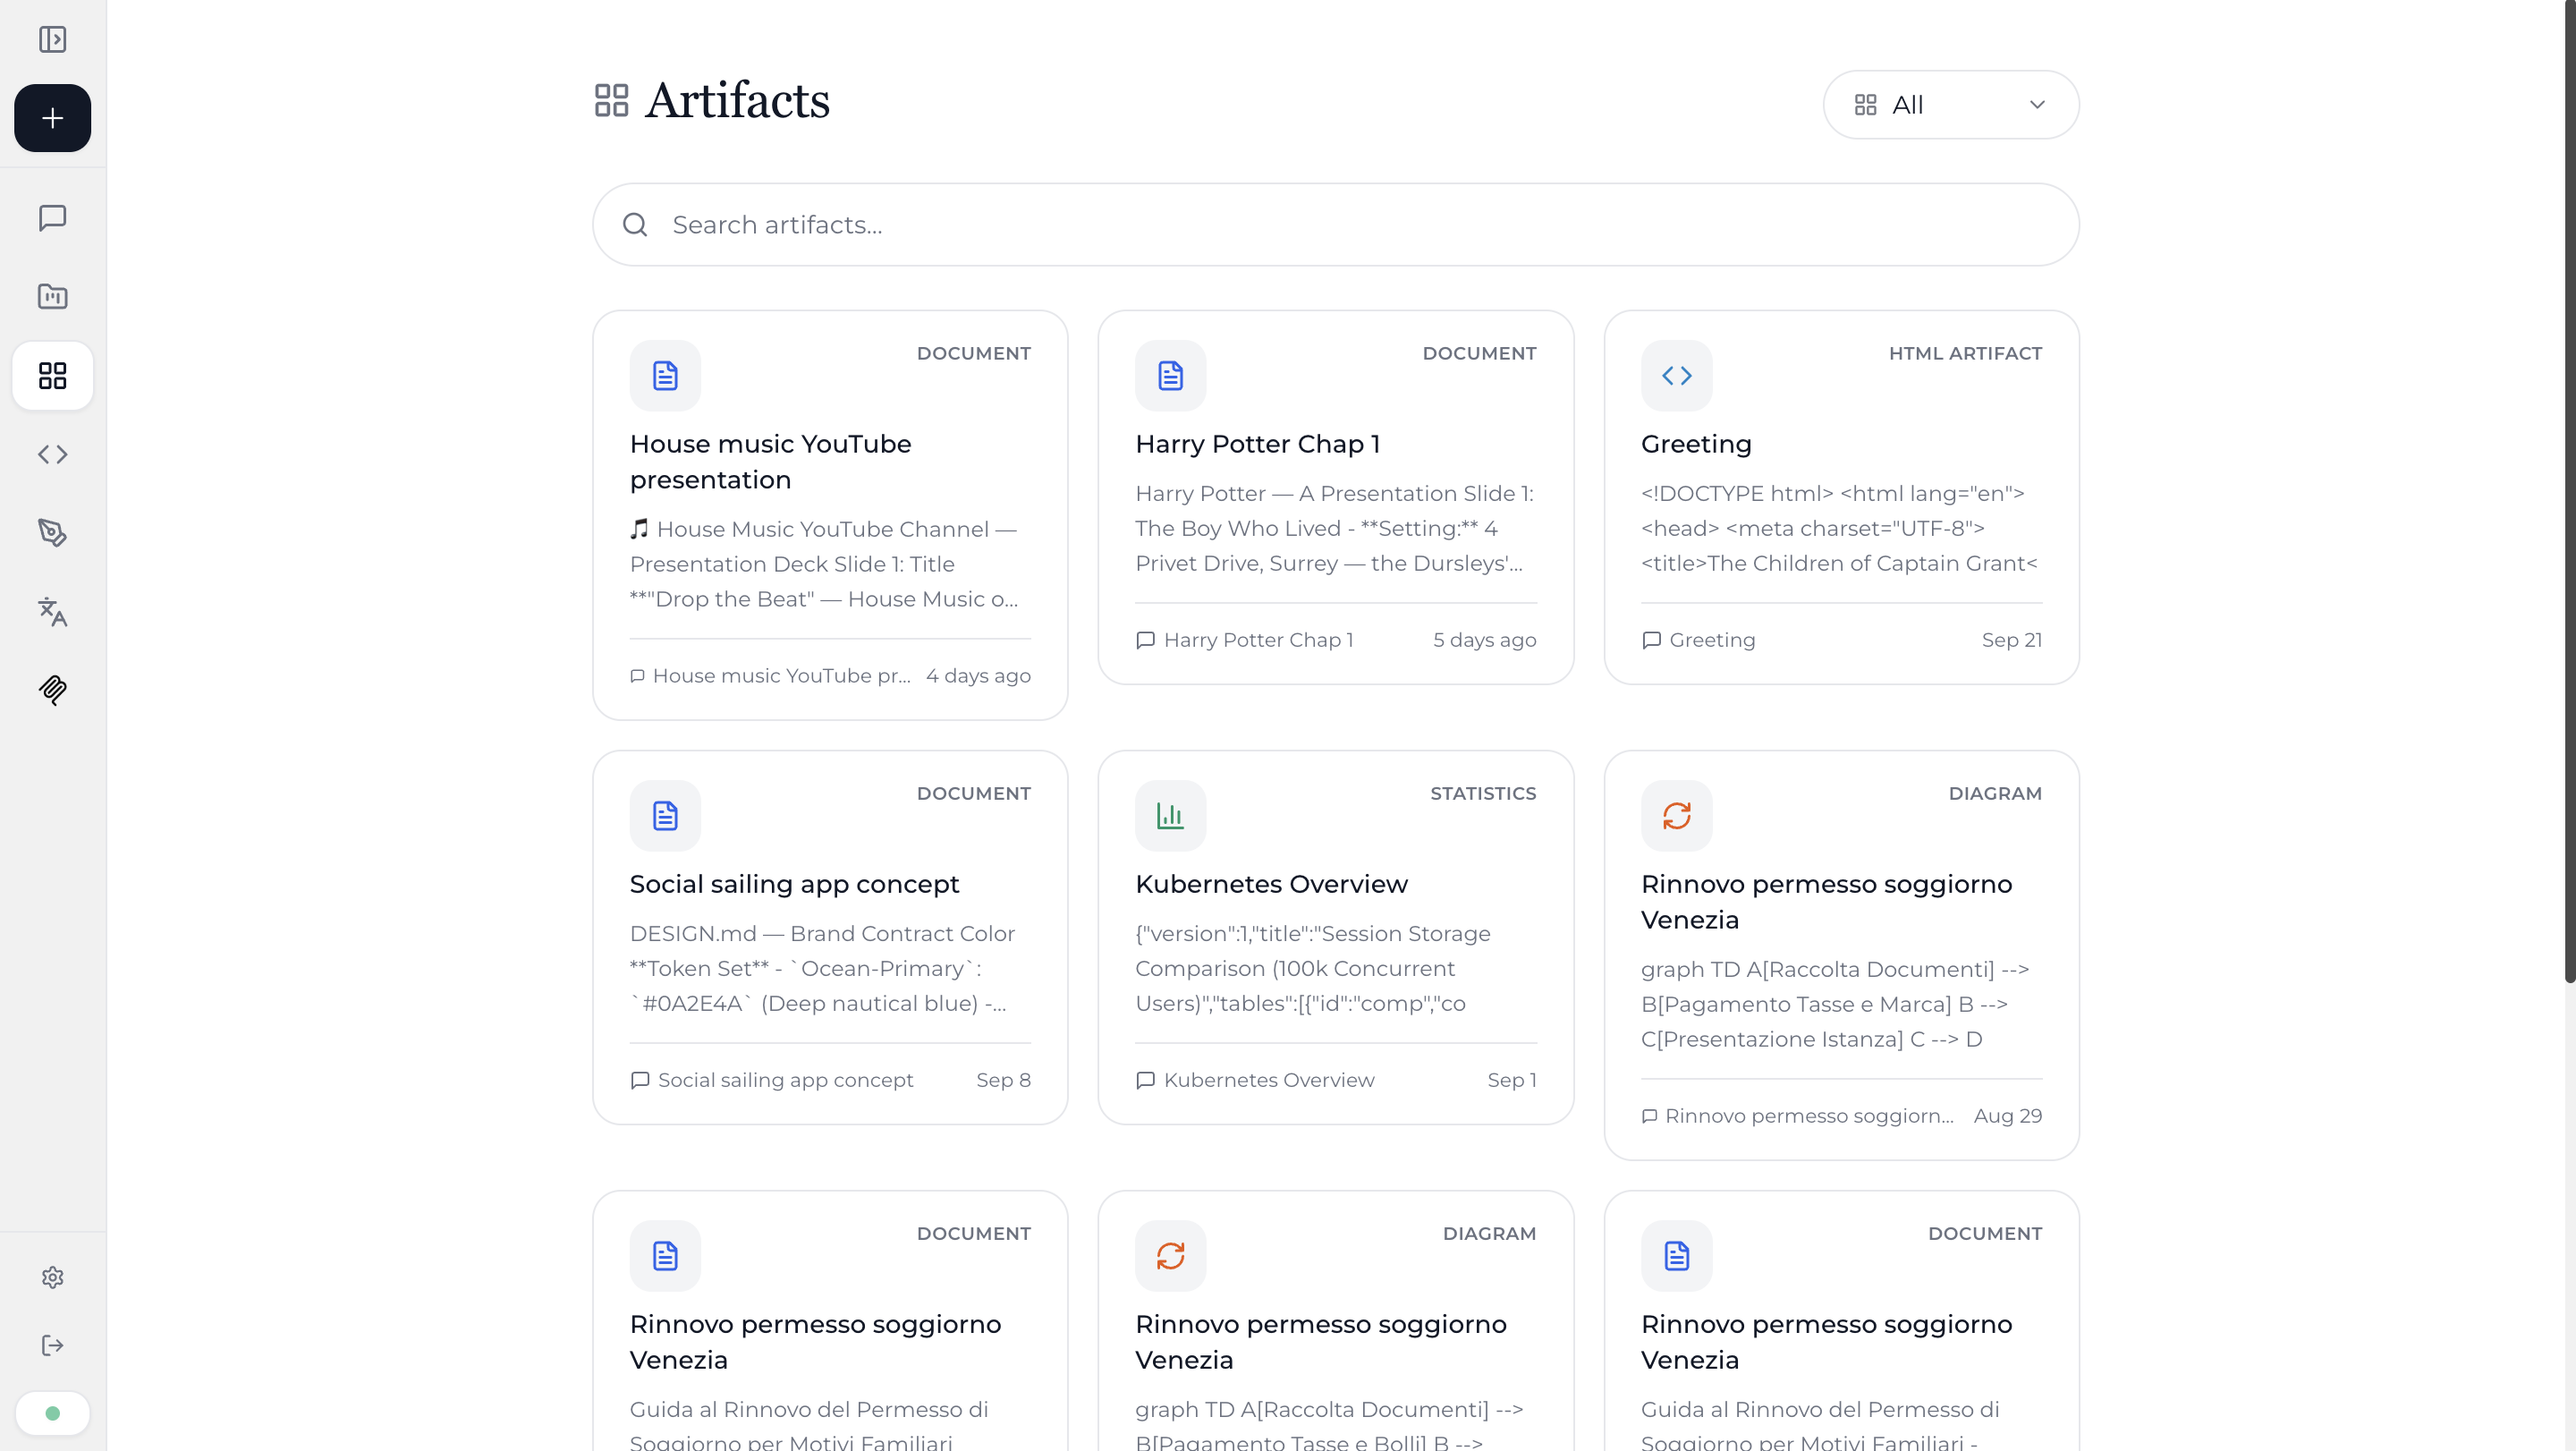
Artifacts

Structured outputs from any hub — tables, charts, and documents you can export or reopen later.

Your perimeter

Runs where you do.

Every component ships in your Docker Compose stack. Inference hits model endpoints you operate. Turn on air-gap mode and outbound access is disabled at the application layer.

Air-gap mode

Web search is disabled at the source, model weights load from local cache, and the data-analysis sandbox runs with networking switched off entirely.

Your models, your silicon

Point Eleftheria at any OpenAI-compatible endpoint. Chat, embeddings, and reranking are configured independently, so you can mix model sizes per workload.

Isolation by default

Each user gets their own coding workspace on disk. Spreadsheet analysis executes in a throwaway container with no network route out.

Eleftheria architecture inside your network boundary Public internet Your network nginx TLS + static FastAPI app + RAG Postgres + pgvector embeddings & history llama-server your models OpenCode coding agent No outbound calls · No telemetry · No vendor account
Models & API

Your models. Your keys. Your rules.

Bring your own OpenAI-compatible inference, govern what each group can call, and automate the platform with bearer tokens — local-first, with optional cloud providers when egress is allowed.

Bring your own models

Point chat, embeddings, and reranking at vLLM, llama-server, Ollama, or any OpenAI-compatible endpoint you operate.

Provider registry

Local is the default. Optionally register OpenAI, Gemini, DeepSeek, Groq, or Azure when your policy allows outbound traffic.

Per-group permissions

Map LDAP groups to model catalogs and hub access so teams only see the inference you approve.

API keys

Issue wbr_ bearer tokens for REST and WebSocket scripting — the same auth boundary as the web UI.
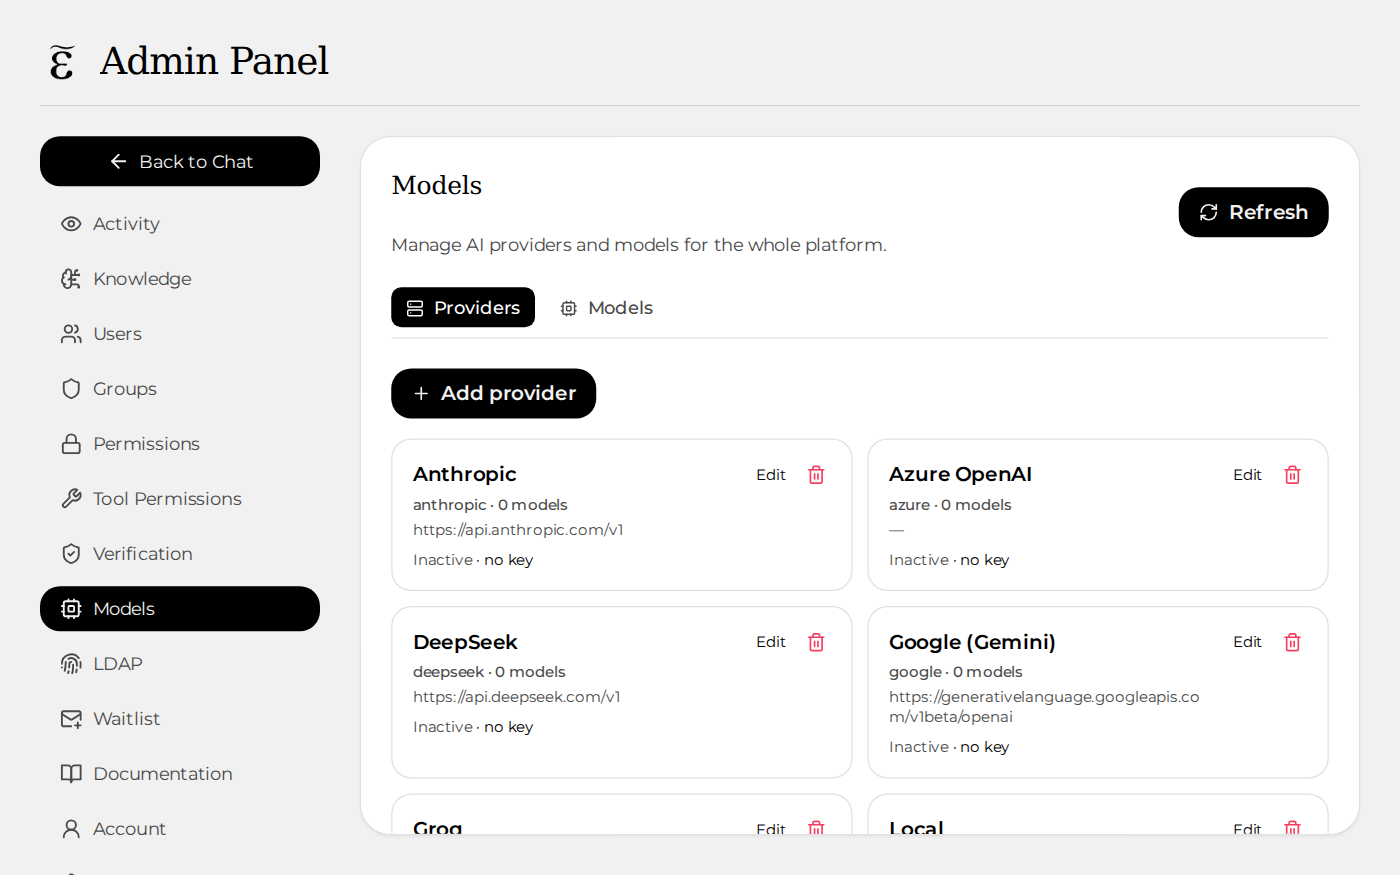
eleftheria.internal / models
Model catalog & providers assets/hub-models.png · 1400×875
Platform

Built for more than one person.

Eleftheria is a multi-tenant deployment, not a desktop toy. Identity, permissions, and auditing are part of the product rather than an enterprise upsell.

Answer verification

Run a response past several verifier models and a judge, then surface a confidence rating next to the answer.

Knowledge Archives

Curated document collections, maintained centrally and attachable to any conversation.

LDAP & Active Directory

Authenticate against directory infrastructure you already run, and map existing groups straight onto Eleftheria roles.

Per-group model permissions

Decide which groups reach which models, and gate the Code and Design workspaces independently per user.

Sandboxed analysis

Spreadsheets are handled by a pandas agent inside a container with no network access.

Everything exports

Conversations to Word, artifacts to PDF and Excel, designs to PNG, PDF, and HTML, projects to ZIP. Nothing is trapped in the product.

MCP tool servers

Register Model Context Protocol servers once and expose them to chat and coding agents under the same permission model.

The trade

What you give up by staying home.

An honest comparison. Hosted suites ship faster and have bigger models. Eleftheria gives you the one thing they structurally cannot.

Hosted AI suites
Someone else's computer
Your documents are processed on infrastructure you cannot inspect
Models change under you, with no way to pin a version
Offline is not a supported state
Per-seat pricing that scales with your headcount
Data residency is a contract clause, not an architecture
vs
Eleftheria
Your computer
Documents are embedded and stored in your own Postgres instance
You choose the weights and upgrade on your schedule
Air-gap mode is a first-class, tested configuration
Add users without adding invoices
Data residency is wherever you racked the server
Pricing

Software licence. Your infrastructure.

On-premise licence for European teams. You run the hardware and models — we licence the workspace. Prices in EUR, net of VAT.

Full data sovereignty · Air-gap capable · GDPR DPA included · Reverse-charge VAT for EU B2B

Starter

Core platform for small teams

€490 / month

€5,880 / year · up to 25 users

  • Chat, RAG & Knowledge Archives
  • Multi-model registry & MCP
  • LDAP / AD & air-gap mode
  • Email support (48h)
Join waitlist

Professional

Add AI translation workflows

€990 / month

€11,880 / year · up to 50 users

  • Everything in Starter
  • Vostok Translate hub
  • Glossaries & bilingual export
  • Email support (24h)
Join waitlist

Enterprise

Unlimited scale, dedicated support

Custom

Unlimited users · from €48,000 / year

  • All modules + custom integrations
  • Dedicated CSM & SLA
  • On-site & AI Act assessment
  • Public-sector discount available
Talk to sales

~€20 / user / month effective across paid tiers. Module add-ons from €3–€6 / user / month. LLM inference costs are yours — local or cloud providers you configure. Annual billing default; monthly +15%.

Questions

Before you ask

Only if you let it. Web search is the single feature that reaches outward, and air-gap mode disables it at the application layer. Inference goes to endpoints you configure, which are normally containers in the same Compose stack. There is no telemetry and no vendor account.
The application tier is modest — FastAPI, Postgres, and nginx run comfortably on a small server. The real requirement is whatever GPU capacity your chosen models need. Because chat and embedding endpoints are configured separately, you can run a large chat model on one machine and a small embedding model elsewhere.
Anything behind an OpenAI-compatible API. The provider registry defaults to local llama-server or vLLM; you can add optional cloud providers when egress is allowed. Embeddings default to BGE-M3. Swapping a model is a configuration change, not a migration.
The retrieval pipeline, the coding agent with real filesystem and git access, the design studio that emits working prototypes, and the multi-user permission layer. A chat wrapper gives you a text box. Eleftheria gives you three production workspaces that share state.
Yes. Build mode has shell and file-write access inside a workspace scoped to that session and user. Plan and Ask modes are read-only by design, so you can investigate a codebase with no risk of modification.
It stays on your disks, because it never went anywhere else. Chats export to Word, artifacts to PDF and Excel, designs to PNG, PDF, and HTML, and code projects to ZIP. The database is ordinary Postgres you can dump.
LDAP and Active Directory integration is built in, including group mapping onto roles and model permissions. Local username and password accounts also work, with registration toggleable.
The whole stack is a Docker Compose file. Bring up the services, point the configuration at your model endpoints, and open the app in a browser.
Yes. Create API keys in the admin UI — wbr_ bearer tokens work against REST and WebSocket endpoints with the same group permissions as your user account.
Yes. The Translate hub runs document and text translation on your configured models, with the same local-first privacy guarantees as chat — no third-party translation API required.

Keep the work. Keep the data.

One deployment. Seven hubs. Nothing leaving the building.

Join the waitlist

Eleftheria is rolling out to teams one deployment at a time. Leave an email and we will get in touch about access.

Stored on our own server. No third-party trackers, no mailing lists.

You are on the list

Thanks — we have your address and will reach out when a slot opens for your team.